AI Frontier Research & Engineering
Tracking emerging technology, dissecting system architecture, and publishing what I actually build and evaluate.
Article archive — page 8
- Anthropic's Latest Research: The State of Agentic Coding and the Persistent Value of Domain Expertise
Anthropic releases a privacy-preserving analysis of 400,000 Claude Code interactions. The research reveals the true division of labor for AI coding agents: humans decide 'what to do', while AI decides 'how to do it'. More importantly, success depends not on 'coding ability', but on 'domain expertise'. This has profound implications for the future of knowledge work.
- OpenAI Deployment Simulation: Predicting LLM Safety Before Launch
Read OpenAI Deployment Simulation: why offline eval and real deployment diverge, and what this simulation can and cannot predict.
- What Is PixelRAG: Retrieval Over Webpage Screenshots
PixelRAG shifts retrieval from plain text to webpage screenshot pixels. This post covers what it solves and where the evidence stops—not a "screenshots beat text" slogan.
- Open Knowledge Format (OKF) v0.2: Provenance and Portable Agent Knowledge
An engineering guide to OKF v0.2 Markdown bundles, provenance, verification, lifecycle fields, attested computation, and boundaries with RAG and LLM Wiki.
- How to Use Zellij: Shortcuts, Clipboard, and Sessions
A current-default reference for Zellij Pane, Tab, Resize, Scroll, Session, clipboard, and mouse operations, including the impact of custom keybindings.
- How to Read Harness Engineering: Setup and Verification for Long-Running Agents
A reading map for long-running agent harnesses—setup, verification, handoff—and how to read related notes on this site.
- Harness Engineering Explained: Martin Fowler's AI Coding Workflow
Harness Engineering, in Martin Fowler's terms, means outer control loops around coding agents—feedforward guides plus feedback sensors—so trust is designed control, not a feeling.
- LangChain Dissects Agent Harness: From Model Capabilities to Deliverable Work Engines
A deep dive into LangChain's long-form article: The formal definition of Harness, the component chain deduced from expected behaviors (Files, Bash, Sandbox, Memory, Context Rot, Ralph Loop), and the insights from model-harness co-training and Terminal Bench.
- Mitchell Hashimoto's Six Stages of AI Adoption: From Dropping Chatbots to Harness Engineering
A deep dive into Hashimoto's firsthand journey: three stages of tool adoption, redoing commits for practice, off-peak and slam dunk delegation, AGENTS.md and verifiable tools, plus the current state and limitations of 'always having an Agent running'.
- 16 Parallel Claudes Building a C Compiler: Anthropic's Agent Teams and Long-Running Harness Experiments
A deep dive into Nicholas Carlini's experiment: nearly 2,000 sessions, about $20,000 in API costs, and a 100,000-line Rust compiler capable of compiling Linux 6.9—exploring task locking, test harnesses, GCC oracle, multi-role specialization, and capability boundaries.
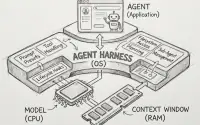
- Phil Schmid: Why Agent Harness Is More Important Than Model Leaderboards in 2026
Deep dive into the Jan 2026 article: durability, OS analogies, system evaluation gaps, lightweight Harness under the Bitter Lesson, and hill climbing alongside training-inference convergence.
- Parallel.ai Popular Science: Agent Harness is the Entire Lifecycle Beyond the Model
Deep dive into Parallel's long article: From intent capture, tool execution, context compilation to verification and persistence, clarifying the differences between Harness, orchestrator, and framework, and comparing with Anthropic / LangChain examples.
- Ignorance.ai Playbook: The Converging Harness Practices of OpenAI, Stripe, and OpenClaw
An in-depth review of the February 2026 horizontal roundup: an engineer's work splitting into 'building the environment' and 'managing Agents', architecture as guardrails, tools as feedback, AGENTS.md as system records, and the separation of planning and execution.
- HumanLayer: The Skill Issue of Coding Agents—Practical Implementation of Five Types of Harness Configurations
In-depth read of HumanLayer's long article: Failure is often a configuration issue, not a model one. Clarifying AGENTS.md, MCP, Skills, Sub-agents, Hooks, and back-pressure, and responding to ETH research and post-training overfitting debates.
- The New Rules of Startups in 2026: Why 'Building Capability' Is No Longer the Core Competency
Standing at the startup scene in 2026, we are witnessing an unprecedented paradigm shift. In the AI-native era, development costs and time are extremely compressed, and the bottleneck for startups is no longer 'building capability,' but 'selection capability.' This article reveals the most disruptive core insights in the AI-driven startup ecosystem.
- Agentic RAG: When Vector Search Meets Agentic Reasoning
An engineering walkthrough of agentic RAG: account-policy confusion, hybrid recall, bounded verification, evidence tracing, and a scoped first-party 100-question evaluation.
- Harness Design for Long-Running AI Engineering: Generation, Evaluation, and Verification Chains
A source-grounded engineering guide to Anthropic's long-running application harness, including the planner-generator-evaluator contract, context reset trade-offs, and reported costs.
- Long-Running Agent Harnesses: Handoffs, Verification, and Recovery
A source-grounded analysis of Anthropic's initializer, progress artifacts, feature inventory, Git checkpoints, and end-to-end verification pattern for work spanning context windows.
For speaking invitations, internal engineering sessions, or architecture exchange, see the topics and public work I can bring into the conversation.
Speaking & contact