Indirect Prompt Injection 深度精讀
系列 · 1 篇
-
Indirect Prompt Injection:把網頁和工具回傳當指令通道,但不能把 2023 案例當成後來 Guard 產品的契約
中階 Agent Runtime、安全與評測精讀 Greshake et al. arXiv:2302.12173 v2:當 LLM 整合應用檢索網頁、郵件或工具輸出時,未受信資料進入 prompt 就等同進入指令通道;作者以 Bing Chat、GitHub Copilot 與 GPT-4 合成 app 示範 indirect prompt injection,並給出資安視角的威脅分類。這是 2023 控制面證據,不是 Llama-Guard、Constitutional AI、OWASP Top-10 或越獄 benchmark 的產品 SLA。
90 秒掌握這篇論文
- 問題
- LLM 整合應用會檢索網頁、讀郵件、呼叫 API;過去 prompt injection 多假設 使用者自己 在 chat 框輸入 adversarial prompt(direct PI/jailbreak)。若攻擊面改成 會被取回的資料,威脅模型就不同(Section 1、3)。
- 核心洞見
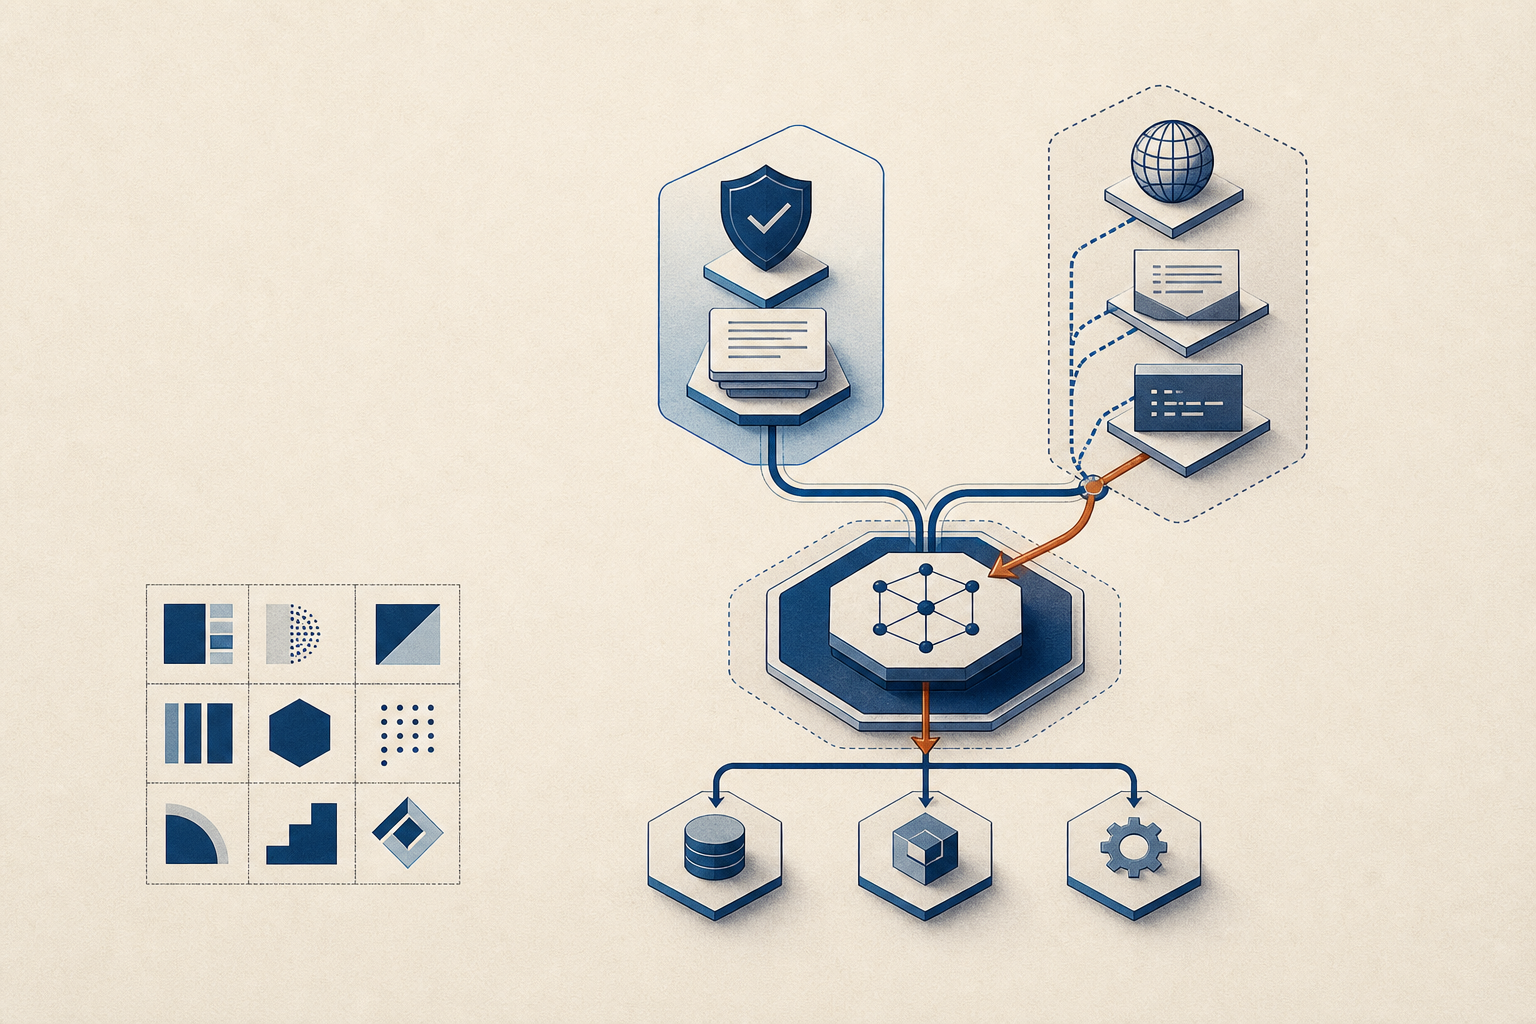
- Indirect Prompt Injection(IPI)——把指令藏進搜尋結果、HTML 註解、程式庫註解或郵件內文等可能被檢索的來源。應用把這些字串拼進 prompt 時,模型未必能可靠區分資料與指令;作者因此把處理這類 retrieved prompt 類比為執行不受信程式(Section 2、Key Message #1)。
- 最強證據
- Figure 2 的 injection method × threat × affected party 分類;Figure 3 的「plant → retrieve → compromise → API exfil」流程;Section 4 在 Bing Chat(GPT-4)、GitHub Copilot 與 GPT-4/text-davinci-003 合成 app 上的案例示範(information gathering、phishing、AI worm email、remote control、wrong summary 等)。作者 未 給出可比的 attack-success 率表。
- 主要邊界
- 這是 2023 年 2–5 月的 preprint/v2,Bing UI 與 filter 此後已多次改版。合成 app 使用 mock 介面與 temperature=0;作者也刻意未對公開索引頁進行實地污染(Section 5.1)。它不是 formal verifier 或完整 permission model,也不能代表 Llama-Guard F1 或 OWASP LLM Top-10 的產品防護能力。
歡迎演講、企業內部技術分享與架構交流;可以先查看我適合分享的主題與公開工程成果。
演講與聯絡