Agent Training and Rewards
Series · 1 posts
-
DRACO: Sending Long-Horizon Agent Credit Back to the Steps
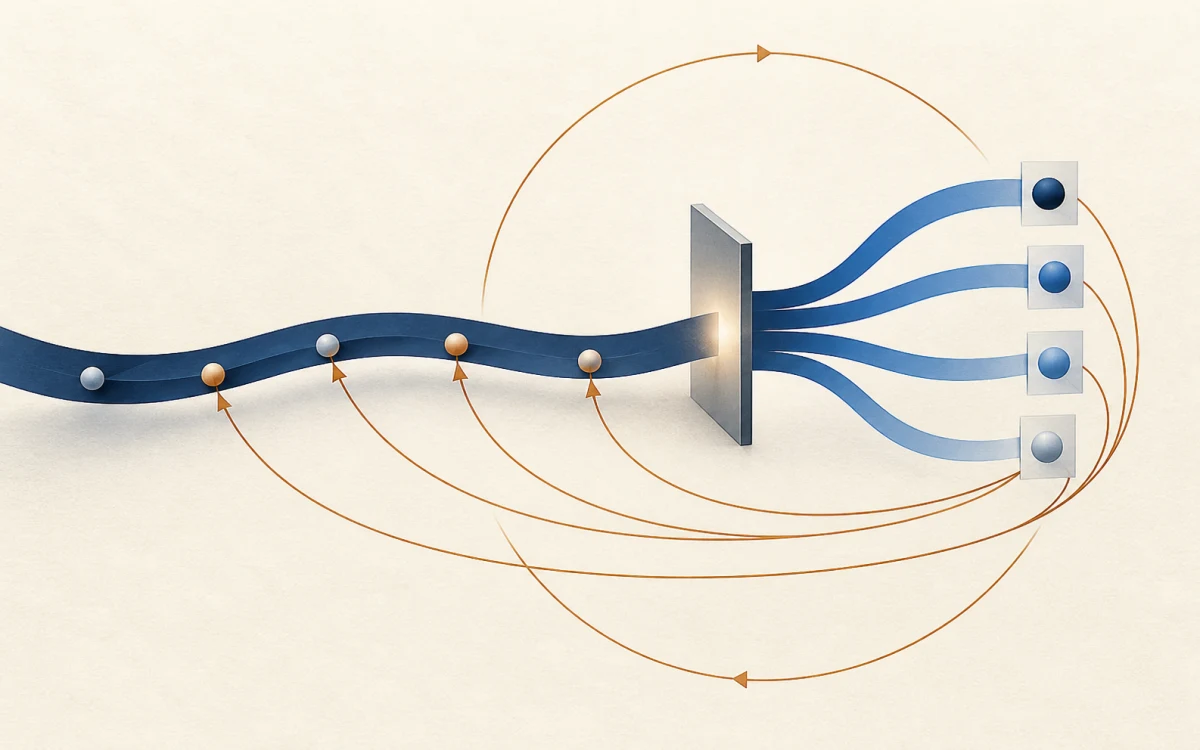
Advanced Agent runtime, safety, and evaluationA source-grounded reading of DRACO (arXiv:2609.04094): dynamic per-trajectory rubrics create an outcome-blind reward, then a closed-form rule redistributes GRPO advantage to the steps cited by the judge.
Understand it in 90 seconds
- Problem
- How can an agent be trained without an outcome oracle, and how can the resulting signal avoid treating a long trajectory as one indivisible action?
- Core insight
- Generate, merge, deduplicate, and filter rubrics dynamically for a task and sampled rollout group. Ask the judge to cite the steps behind each verdict, then redistribute the trajectory advantage to those steps with a closed-form rule.
- Strongest evidence
- With Qwen3.6-27B, AppWorld test-normal TGC/SGC rises from 69.4/41.1 for the base policy to 85.3/70.6 for DRACO. Against the same-budget outcome-reward reference, the margins are +5.3/+11.3 points (Table 2, Section 4.2). Zero-shot tau-bench Banking success rises from 15.8 to 20.4.
- Main boundary
- These are benchmark and end-task results, not direct validation of the judge or of step causality. The authors have no human-rater calibration; a judge may be consistently wrong, and a wrong attribution can still produce a better policy by chance.
For speaking invitations, internal engineering sessions, or architecture exchange, see the topics and public work I can bring into the conversation.
Speaking & contact