Original Speculative Decoding deep reading
Series · 1 posts
-
Speculative Decoding: Draft with a Small Model, Verify in Parallel, but T5 Speedups Do Not Represent Every Serving Stack
Intermediate Build the foundations firstA source-grounded reading of Leviathan et al., ICML 2023 / arXiv:2211.17192: a cheap draft model M_q proposes tokens, the target model M_p verifies a chunk in parallel, and rejection sampling keeps the output distribution identical to target-only decoding. T5-XXL 11B reaches 2.3X-3.4X wall-clock speedup on T5X; this is 2023 lossless inference-algorithm evidence, not a GPTQ, FlashAttention, vLLM, Medusa, or EAGLE contract.
Understand it in 90 seconds
- Problem
- Decoding K tokens from a large autoregressive Transformer takes K serial forward passes; each step is often limited by memory bandwidth rather than raw arithmetic throughput, leaving spare parallel capacity idle (Section 1).
- Core insight
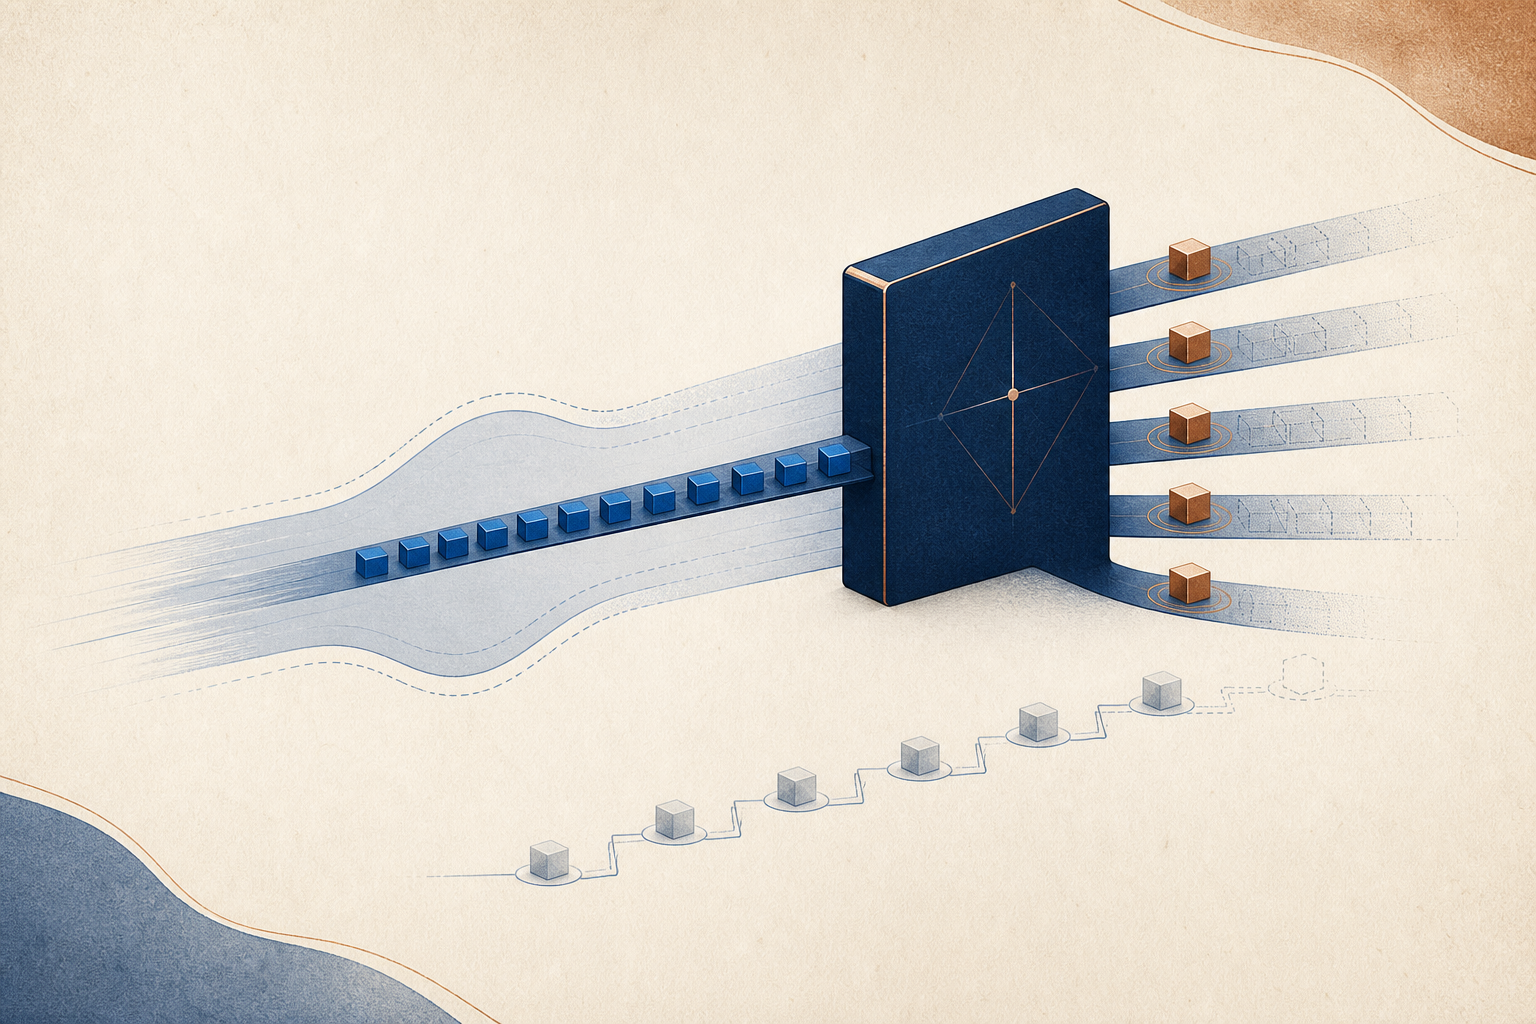
- Speculative Decoding lets a small model Mq autoregressively draft gamma tokens, then runs the target model Mp in parallel on the prefix through each draft position to obtain distributions p1 through p{gamma+1}. Speculative sampling (rejection sampling plus an adjusted distribution) decides how many drafts to accept and adds one token guaranteed to come from Mp. The control point is lossless parallel verification versus step-by-step target-only decoding; the output distribution is identical to Mp alone (Algorithm 1, Appendix A.1).
- Strongest evidence
- T5-XXL 11B as Mp and off-the-shelf T5-small 77M as Mq versus the T5X baseline, batch=1, single TPU-v4 (Table 2): WMT EnDe 3.4X (temp=0, gamma=7, alpha=0.75) and 2.6X (temp=1, alpha=0.62); CNN/DM 3.1X and 2.3X. The abstract and Section 4 also report a 2X-3X band relative to T5X.
- Main boundary
- You need a task-aligned draft model and compute that can host gamma+1 parallel Mp forwards; total arithmetic operations can rise (Sections 3.4 and 6). This is a 2023 Google T5X experimental contract, not a vLLM or TensorRT-LLM product SLA, not GPTQ bitwidth, and not Medusa or EAGLE draft heads. InstructGPT 85±3% win rates, Transformer WMT BLEU, and YOLO mAP are not in this PDF.
For speaking invitations, internal engineering sessions, or architecture exchange, see the topics and public work I can bring into the conversation.
Speaking & contact