Agent Canvas Editing and Evaluation
Series · 1 posts
-
ACE: Let a Canvas Agent Understand Structure Before It Corrects Itself
AdvancedA deep reading of ACE (arXiv:2608.24103 v1): hierarchical scene graphs, CARE routing, and an instruction-following judge turn multi-slide editing into a scoped, diffable, rollback-aware loop, with explicit limits around benchmarks, human raters, mock mode, and live reproduction.
Understand it in 90 seconds
- Problem
- PowerPoint- and HTML-like flat, absolute-positioned documents encode objects as many coordinates. Adding one element can force an agent to recompute other positions, while a valid alternative design can be penalized by reference-diff metrics.
- Core insight
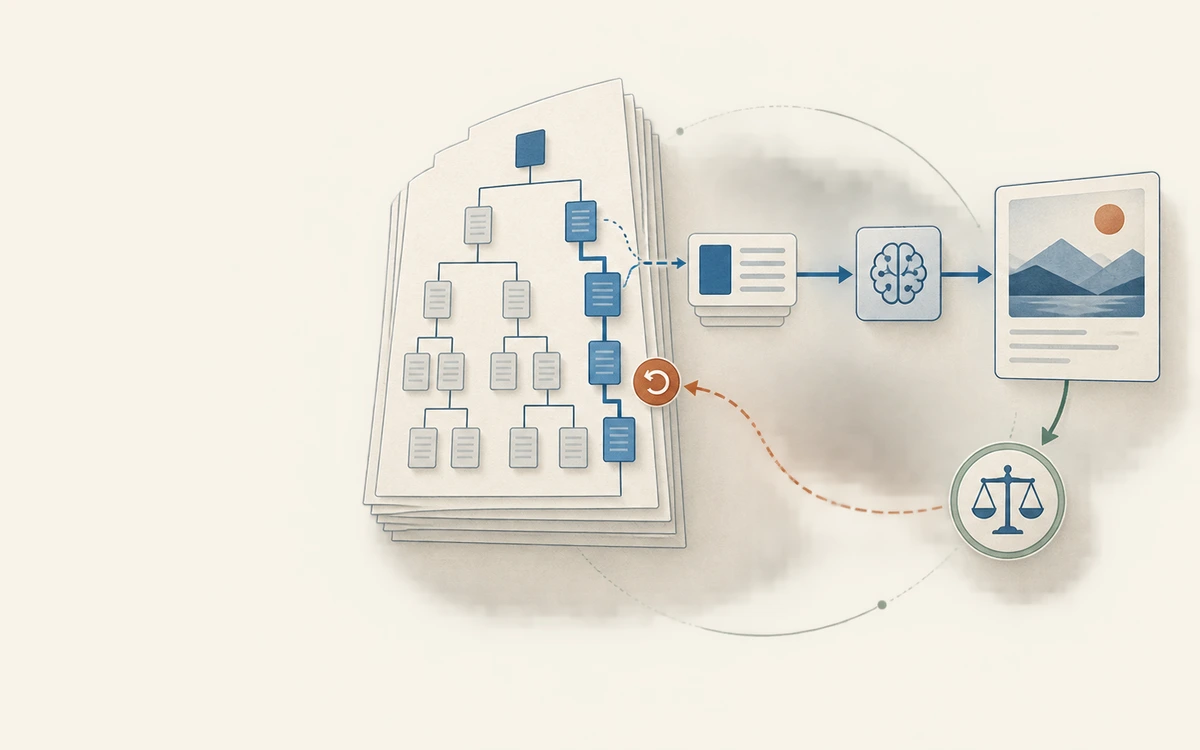
- ACE uses a hierarchical scene graph with parent–child relations, relative transforms, and auto-layout, then maps intent to structured operations through 98 specialized tools. CARE exposes only a relevant slide, node structure, or design token. After an edit, JsonDiff compares the original and current state, and a ground-truth-free instruction-following judge supplies the next critique.
- Strongest evidence
- On the full 94-task benchmark, GPT IF is 4.23 for ACE versus 3.81 for the HTML baseline, with paired p=.010; reported speed is about 1.75x and cost about 44% lower. On that same full set, VQ is 3.66 versus 3.57 with p=.56, so the headline is not universal visual-quality improvement.
- Main boundary
- Twenty-six blind raters give ACE versus HTML a 58.7% decisive overall win rate; self-corrected output versus single-pass is 81.5%. The panel is small, ties are common, agreement is low to moderate, and judge circularity remains. The paper does not show universal creative-editing improvement or that a judge can replace a designer.
For speaking invitations, internal engineering sessions, or architecture exchange, see the topics and public work I can bring into the conversation.
Speaking & contact